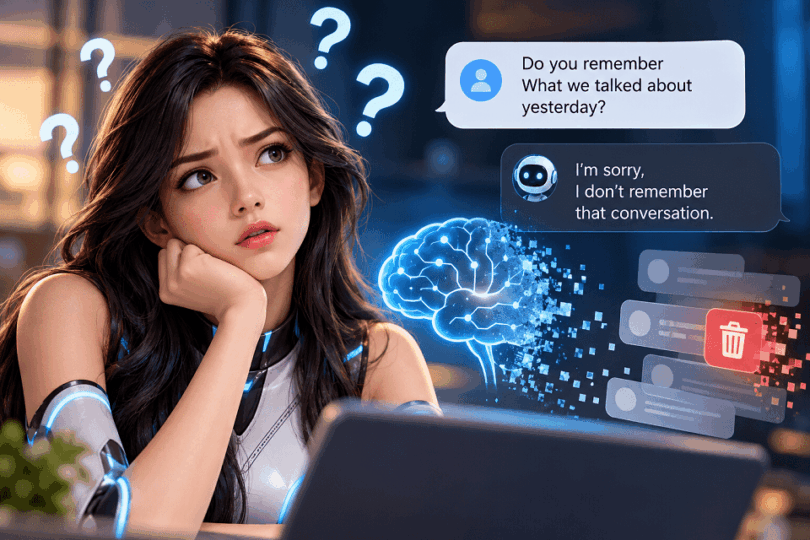

AI characters can forget conversations even when a platform saves chat history or offers persistent memory. Why do AI characters forget conversations? Usually, relevant information is missing from the active context, was never saved, was not retrieved, or was available but not used correctly in the reply.
Most language models do not maintain a human-like, complete record of every interaction. Instead, an application supplies selected information, such as recent messages, character instructions, summaries, and saved memories. If an important fact is missing from that input—or the model contradicts it—the character may appear to have forgotten.
The fix depends on where the failure occurs. A context limit, missing saved memory, failed retrieval, and an inconsistent answer are different problems. This guide shows you how to distinguish them before changing settings or rewriting a character.
You will learn how AI character memory works, the seven common causes of forgetting, a four-checkpoint diagnostic method, and practical fixes for relationships, promises, and cross-session continuity.
Why Do AI Characters Forget Conversations?
AI characters forget conversations when relevant information is no longer available in the model’s active context, is not preserved in persistent memory, or is not retrieved and used correctly when generating a response. Most language models generate each reply from the information supplied during inference rather than maintaining a complete, continuously accessible record of every past interaction.
Several technical mechanisms can cause this behavior. A context window may exclude older messages when the conversation exceeds its token budget. A summarization process may discard specific facts while compressing conversation history. A memory retrieval system may fail to return a relevant record, or the model may generate an incorrect response despite receiving the correct information.
These mechanisms represent different failure points in the conversational pipeline. A saved conversation does not guarantee active recall, and persistent memory does not guarantee that a stored fact will influence every response. To identify why an AI character forgets a detail, it is necessary to distinguish context limitations, memory storage and retrieval problems, and errors during response generation.
How AI Character Memory Works
AI character memory is not a single capability built into every language model. It is usually the result of several mechanisms working together: context management, conversation-history storage, persistent memory, retrieval, and prompt construction. The exact architecture depends on the platform, the underlying model, and the application’s implementation.
When a user sends a message, a typical AI character system follows a processing pipeline similar to this:
- Conversation input
The latest message and available chat history
- Memory and history retrieval
Load relevant messages, saved facts, or summaries where supported
- Context and prompt construction
Combine character instructions, conversation context, and retrieved information
- Model inference
Generate a response from the supplied tokens
- Response and state update
Return the reply and save conversation or memory updates if implemented
Conceptual architecture. Actual processing order and components vary across platforms.
Understanding these stages helps explain why an AI character can appear to forget something even when the original conversation still exists.
Context window and active conversation
A language model processes input as tokens rather than accessing an unlimited conversation transcript. The context window defines the maximum token capacity available for the model’s input and generated output, subject to the model’s specific limits.
The active context may include system instructions, character definitions, previous messages, retrieved memories, and other metadata. If the conversation grows beyond the available budget, the application may truncate messages, summarize history, or select a subset of earlier content.
Consequently, a fact can remain in the stored transcript while being absent from the context used to generate the current response.
Persistent memory and conversation storage
Conversation storage and persistent memory serve different purposes. Conversation storage preserves chat messages so that a session can be reopened or reviewed. Persistent memory retains selected information for potential use in future responses.
A platform might store a fact such as a user’s preferred name, a character’s relationship, or an important event. Depending on its design, this information may be represented as structured records, text summaries, embeddings, or another storage format.
However, saving a fact does not guarantee that the application will retrieve it for every relevant question.
Memory retrieval and prompt construction
When a platform supports external or persistent memory, it may retrieve information using keywords, metadata filters, semantic similarity, or a combination of methods. The application then decides which results to include in the prompt.
This introduces two distinct failure possibilities: the correct fact may not be retrieved, or it may be retrieved but omitted from the final context because of relevance filtering or token-budget constraints.
Even when the correct fact reaches the model, generation is not guaranteed to be accurate. The model may overlook the information, interpret it incorrectly, or produce a conflicting answer.
Why the distinction matters
Consider a character whose stored memory identifies its sister as Emma. If the character later gives her a different name, several explanations are possible:
- The fact was never saved.
- The fact was saved but not retrieved.
- The fact was retrieved but excluded during prompt construction.
- The fact was included in the prompt, but the model generated an incorrect response.
These failures may look identical to the user, but they occur at different stages of the system.
The key point: AI character memory depends on the entire information pipeline, not just the language model’s context window. Effective troubleshooting requires identifying whether the information was stored, retrieved, supplied to the model, and used correctly.
Stateless Inference, Session Boundaries, and Visible Chat History
Many language-model requests are stateless: the model generates each response from the input supplied for that request rather than automatically carrying a complete record of earlier exchanges. The application can create continuity by sending selected prior messages, summaries, or saved memories with each request. A chat log can remain visible in the interface even when only recent messages or selected memories reach the model. Closing and reopening a chat may restore the transcript without restoring every detail to the active context. Conversation history records what was said; persistent memory attempts to preserve selected information for later use. The two can share storage, but they serve different purposes and can fail independently.
Retrieval-Augmented Generation and External Memory
Some AI applications use retrieval-augmented generation (RAG) or a related retrieval system. The application stores information outside the model, searches that information when a new message arrives, and adds selected results to the prompt. The stored material might include summaries, character facts, relationship details, or earlier events. Retrieval can make older information available without placing the entire transcript in every request.
RAG is not a guarantee of perfect recall, and not every character platform uses it. Retrieval may miss a fact, return an outdated version, select a similar but incorrect record, or return more material than the context budget can accommodate. Even when the right record is supplied, the model can still misunderstand or ignore it. A useful diagnosis therefore checks both what is stored and what is actually retrieved for the current response.
Why the Model Does Not Automatically Learn From Each Conversation
In ordinary inference, a model’s underlying parameters are not updated every time a user sends a message. The model responds using its trained parameters and the context provided for that request. A platform may save new facts to an external memory store, update a conversation summary, or personalize later prompts, but those actions are different from changing the model through training. Unless a service explicitly describes a training or fine-tuning process, users should not assume that telling a character something permanently teaches the underlying model.
This distinction explains why a character can use a new fact correctly moments after it is mentioned but fail to recall it in a later session. The fact may still be present in the active context of the first exchange, while no persistent record was created or retrieved for the second.
Can AI Characters Remember Past Conversations?
Yes, some AI character applications preserve selected information across conversations, but this depends on their features and settings. Three things must be distinguished: a saved transcript, a persistent memory record, and the information actually supplied to the model for a particular reply. A visible chat log does not prove that every message is available to the model, and a saved memory does not guarantee that it will be retrieved or used correctly. To test cross-session recall, use a distinctive, non-sensitive fact, check whether the platform saves it, and ask about it in a new chat without repeating the answer.
7 Common Reasons AI Characters Forget Conversations
AI character memory failures can originate at different stages of the conversational pipeline. A fact may never be stored, may be lost during context management, may not be retrieved from persistent memory, or may reach the language model without being used correctly. Although these failures can produce similar responses, their underlying causes differ.
The following seven causes examine distinct technical mechanisms, from context-window constraints to application-level persistence failures. Understanding these differences helps identify the appropriate troubleshooting method rather than treating every memory problem as a limitation of the AI model.
1. Context-Window Limits and Message Truncation
How finite token budgets and context-selection strategies remove earlier messages from the active inference context.
2. Lack of Persistent Memory Across Sessions
Why some platforms retain conversation history without maintaining reusable memory between separate chats.
3. Memory Features Are Disabled or Restricted
How unavailable features, configuration settings, and platform-specific limitations affect persistent recall.
4. Important Information Is Never Extracted or Stored
How memory extraction, fact selection, and write operations can fail to preserve important details.
5. Character Definitions and Prompt Instructions Are Inconsistent
How vague character profiles, contradictory instructions, and prompt construction can produce inconsistent behavior.
6. Conversation Summarization and Memory Retrieval Lose Information
How lossy summaries, retrieval-ranking errors, and incomplete context assembly can prevent relevant facts from reaching the model.
7. Session-State and Data-Persistence Failures
How incorrect session restoration, failed writes, stale reads, and synchronization problems can make saved information unavailable.
These causes are related but not interchangeable. For example, a context-window problem concerns the information available within a single inference request, while a persistent-memory problem concerns whether selected information can be carried across sessions. Retrieval failures occur when stored information is not made available when needed, and generation failures occur when the model does not use available information correctly.
The following sections examine each mechanism, its observable symptoms, and the technical reasons it can make an AI character appear to forget a conversation.
1. The Conversation Exceeds the AI’s Context Window
A context window defines the maximum number of tokens a language model can process in a single inference request. In an AI character application, this budget may need to accommodate system instructions, character definitions, conversation history, retrieved memories, metadata, and the tokens generated in the response. The available capacity therefore cannot be treated as space reserved exclusively for chat messages.
Tokens are text fragments rather than complete words. Their count depends on the language, formatting, and tokenizer used by the model. As a conversation grows, the accumulated message history can consume an increasing share of the available context budget.
What happens when the context budget is exceeded?
The application must decide which information to supply to the model. Depending on its implementation, it may truncate older messages, retain only recent exchanges, summarize previous interactions, or select specific messages considered relevant. Some systems combine several of these strategies.
Consequently, the complete conversation may remain in the platform’s database while only a portion of it is included in the prompt for the next response. A fact that falls outside the active context cannot directly influence generation unless it is preserved through another mechanism, such as a summary or retrieved memory.
How context-window limits cause memory failures
Consider a long-running roleplay in which a character’s profile establishes that its sister is named Emma. The user reinforces this detail early in the conversation, but hundreds of messages follow.
If the application retains only recent exchanges, the original statement may eventually disappear from the active context. When the user later asks about the sister, the model may not have the information needed to answer correctly.
This is not necessarily a failure to store the conversation. It is a failure to keep the relevant information available during inference.
Why a larger context window does not guarantee perfect recall
Increasing the context window allows a model to process more tokens, but it does not guarantee that every detail will be retained or used correctly. The application may still limit the history it supplies, and the model may overlook information buried in a long sequence of messages.
Long-context performance also depends on how effectively the model identifies and uses relevant information. Merely fitting a conversation within the token limit does not guarantee accurate recall of every name, relationship, instruction, or event.
How to identify a context-window problem
Look for a pattern in which the character remembers recent exchanges but loses details introduced much earlier in the same conversation. If the platform allows you to inspect the full chat history, compare that history with what the character appears able to recall.
For developers, the most useful diagnostic is to inspect the actual prompt or message sequence sent to the model, including token counts and any truncation or summarization performed by the application. If the relevant fact is absent from that input, the problem lies in context construction rather than necessarily in the model’s ability to generate an accurate answer.
Technical takeaway: A context window limits the information available during an inference request. When older messages are excluded and their important facts are not preserved elsewhere, an AI character can lose conversational continuity even though the original messages still exist in storage.
2. The Platform Does Not Have Persistent Memory
An AI character can use earlier messages within an active conversation without retaining those details for future sessions. This distinction arises because contextual information and persistent memory are separate parts of a conversational AI system. The language model processes the context supplied with each request, while the surrounding application determines whether information is stored and made available across sessions.
Contextual memory versus persistent memory
During an active conversation, the application typically supplies some combination of recent messages, character instructions, and other relevant context to the model. The model can use that information to maintain continuity while it remains available in the prompt.
Persistent memory requires an additional mechanism. The application must preserve selected information beyond the current context and retrieve it when a later conversation needs it. This may involve structured database records, saved summaries, user profiles, or other memory stores.
The distinction becomes clearer when we separate three operations:
- Conversation persistence: Saving the original messages so the user can reopen or review a chat.
- Memory persistence: Retaining selected facts or summaries for potential use in later sessions.
- Memory retrieval: Loading the relevant stored information and supplying it to the model during a subsequent request.
A platform can support conversation persistence without implementing cross-session memory. It can also support persistent memory without making every stored fact available in every conversation.
Why information disappears between sessions
Consider an AI character that learns a user’s preferred name during a conversation. While the chat remains active, the name may be present in the recent message history. When the user opens a new chat, the application may initialize a new conversation without loading that earlier history.
If the name was not stored separately or made available through a supported cross-session mechanism, the model has no reliable basis for recalling it. The original conversation may still be accessible in the user’s chat history, but that does not mean its contents are included in the new session’s prompt.
This behavior may be intentional rather than a software defect. Some platforms isolate conversations by design, while others provide cross-chat memory or allow users to manually transfer character information.
How persistent memory is implemented
Implementations vary, but a persistent-memory workflow may involve extracting selected facts from conversation messages, storing them in a database, and retrieving relevant records when needed. More advanced systems may use semantic search, metadata filters, or ranking algorithms to identify information related to the current query.
For example, the application might store a record stating that a character’s sister is named Emma. When the user later asks about the sister, the application can retrieve that record and add it to the prompt. Without this retrieval step, the existence of the stored record alone does not guarantee that the model will use it.
How to diagnose the problem
Test whether the character remembers a distinctive, non-sensitive fact in the original chat and then in a new session. If it recalls the fact in the original conversation but not the new one, investigate whether the platform supports persistent memory and whether cross-session retrieval is enabled.
For developers, inspect the session initialization process, the memory-store writes, and the records retrieved for the new conversation. This helps distinguish an intentionally isolated session from a missing persistence or retrieval mechanism.
Technical takeaway: Recent conversation context provides short-term continuity, whereas persistent memory allows selected information to survive beyond the active session. Reliable cross-session recall requires the application to store relevant information and make it available to the model when needed.
3. Saved Memories Are Disabled or Not Available
Persistent memory depends not only on the underlying language model but also on the application’s configuration, available features, and memory-management logic. A platform may support storing selected facts while allowing users to disable memory, restrict its use to particular chats, or access only certain memory controls under their current subscription.
When a memory feature is disabled or unavailable, the system may continue generating responses from the active conversation context without incorporating previously saved information. This can make an AI character appear to forget facts even when the platform retains the original conversation or memory records.
Memory Configuration and Feature Availability
Memory-related controls can operate at different levels, depending on the platform:
- Account-level settings: These determine whether memory features are available or enabled for the user’s account.
- Conversation-level settings: A particular chat may have its own memory configuration, pinned facts, or saved context.
- Character-level configuration: Some systems distinguish a character’s permanent background information from memories associated with a specific conversation.
- Feature availability: A platform may not support persistent memory, or a particular feature may not be available to every user.
These settings are not interchangeable. Enabling a memory feature at the account level does not necessarily mean that every chat shares the same memories. Similarly, a character definition may provide consistent background information without preserving events from previous conversations.
How Free and Paid Plans Can Affect Memory
Some AI character platforms differentiate their subscription tiers by memory capacity, memory-management tools, context length, or access to advanced models. However, these differences are platform-specific, and a paid subscription does not automatically guarantee persistent memory or perfect recall.
For example, some platforms provide basic memory controls to free users while reserving advanced memory features for subscribers. The exact differences depend on the platform’s current plans and feature availability.
The important technical distinction is between memory availability and memory effectiveness. A platform may provide a memory feature but still fail to retrieve a relevant fact, include it in the model’s context, or use it consistently during generation.
How to Diagnose a Memory Configuration Problem
If an AI character repeatedly forgets previously established information, check whether the relevant memory feature is available and enabled. Inspect the memory associated with the current conversation and determine whether the missing fact has actually been saved.
If the fact is present in the memory interface but does not influence the response, investigate retrieval and context construction rather than assuming that memory is disabled. If the platform does not offer persistent memory for that use case, you may need to provide the relevant information again or use a supported alternative, such as pinned messages or a character knowledge file.
Technical takeaway: Disabled settings and feature restrictions can prevent an AI character from accessing persistent memory, but an enabled memory feature does not guarantee successful recall. Diagnose feature availability, configuration, storage, and retrieval separately before attributing the problem to the language model.
4. Important Details Were Never Saved to Memory
An AI character can use a fact from the current conversation without ever storing it in persistent memory. This happens because processing a message and creating a durable memory record are separate operations. The language model can use information present in its active context, while the application may independently decide whether that information should be extracted, saved, and made available in future sessions.
For example, a user might establish that a fictional detective lives in London, has a sister named Emma, and is investigating a case involving a missing painting. The character may use all three details correctly during the current conversation. However, if the platform saves only a short summary or extracts only selected facts, Emma’s name or another specific detail may never enter persistent memory.
Why Memory Extraction Can Omit Important Facts
Persistent-memory systems often need to select information from a much larger volume of conversation history. Depending on the implementation, this process may use language-model-based extraction, predefined rules, structured data fields, or a combination of methods.
Several factors can cause important information to be omitted:
- Selective memory extraction: The system may prioritize recurring preferences, major events, or information considered useful for future conversations. A single mention of a character’s relationship or an exact date may not be selected.
- Lossy summarization: A conversation summary may preserve the main storyline while dropping specific names, dates, conditions, or minor events.
- Schema limitations: A structured memory system may have fields for a character’s identity or preferences but no appropriate field for a particular story detail.
- Failed or skipped memory writes: The application may not save an extracted fact because of a processing error, a configuration rule, or a failed storage operation.
- Memory-update conflicts: A newer statement may replace an earlier record, or the system may retain inconsistent versions without resolving which one is current.
These are distinct failure modes. A fact that was never extracted cannot be retrieved from the memory store later, while a fact that was extracted but not successfully written requires a different diagnosis.
Why Recent Recall Does Not Prove Persistent Storage
Suppose a character correctly identifies Emma as the detective’s sister immediately after the user introduces her. That response only demonstrates that the information was available in the active context. It does not establish that the platform created a persistent record.
If the conversation continues and the relevant message eventually leaves the active context, the character may stop recalling Emma’s name. The same can happen in a new session if the application never saved the relationship in the first place.
This explains why an AI character can appear consistent during a short exchange but lose important facts during a longer roleplay. The model may have used the information successfully without the platform ever converting it into durable memory.
How to Diagnose Missing Memory Records
For developers, the most direct approach is to trace a known fact through the memory pipeline:
- Confirm that the fact appears in the original conversation history.
- Inspect whether the memory-extraction process identified it.
- Verify that a corresponding record was written to persistent storage.
- Check whether the record remains available after the session ends.
- Determine whether the retrieval process returns the record for a relevant follow-up query.
If the platform does not expose these internal operations, users can still check its available memory interface, inspect saved notes, or test whether a fact survives in a new conversation.
Technical takeaway: Information used during inference is not automatically persistent memory. Reliable long-term recall requires the application to identify important facts, preserve them successfully, and make them available when a later response needs them.
5. The Character Definition or Personality Instructions Are Weak
An AI character can appear to forget established facts even when those facts remain available in the conversation context. In some cases, the underlying problem is not memory loss but inconsistent instruction conditioning: the character definition, system instructions, retrieved memories, and conversation history may fail to provide a clear, consistent basis for the next response.
For more guidance on writing clear, consistent instructions, see ProDigitalWeb’s Master Prompt Engineering guide.
How Vague Character Definitions Affect Responses
A vague character description leaves important behavioral decisions unspecified. For example, describing a detective as “intelligent, mysterious, and independent” does not establish where the detective lives, which relationships matter, or how the character should respond to a particular situation.
The model may generate plausible details to fill these gaps. If those details change between responses, the character can appear to forget its own background when the underlying issue is that the information was never clearly established.
A stronger character definition distinguishes fixed facts from flexible personality traits. For example:
- Fixed fact: The detective’s sister is named Emma.
- Behavioral rule: The detective avoids discussing family relationships with strangers.
- Personality trait: The detective is cautious and observant.
- Flexible behavior: The detective may become more open with trusted companions.
This structure makes the character’s identity and behavior easier to distinguish. It does not guarantee perfect adherence, but it reduces ambiguity.
How Conflicting Instructions Cause Character Drift
Conflicts can occur when different parts of the prompt describe incompatible facts or behaviors. A character definition might state that the detective never carries a weapon, while an example dialogue repeatedly depicts the detective drawing a pistol. The model receives conflicting signals about the intended behavior.
Similar conflicts can arise between a character profile and newer conversation messages, between different memory records, or between instructions added by the platform and those supplied by the user.
Language models do not necessarily resolve these conflicts using a reliable database-style rule. Their responses depend on the model, the structure and ordering of the instructions, and the surrounding context. As a result, a character may follow one instruction in one response and contradict it in another.
Prompt Construction Matters as Much as Character Quality
The character definition is only one component of the final prompt. The application may combine it with system instructions, recent messages, summaries, retrieved memories, and other metadata.
Even a well-written character profile can become ineffective if important sections are truncated, conflicting information is introduced later, or the prompt does not clearly distinguish instructions from descriptive content.
For example, a memory record may identify Emma as the detective’s sister, while a later summary incorrectly identifies her as a colleague. If both records reach the model without clear conflict resolution, the resulting response may be inconsistent. Improving the character description alone will not fix the underlying data conflict.
How to Diagnose and Reduce Character Inconsistency
Start by checking whether the disputed fact appears in the character definition and whether the instructions contain contradictions. Then determine whether the relevant information remains present in the actual prompt supplied to the model.
For developers, inspect the assembled prompt, the order and source of conflicting instructions, and any truncation applied during context construction. If the correct information is present but the model still contradicts it, controlled tests can help evaluate instruction adherence across different prompt structures and conversation lengths.
For character creators, keep essential facts explicit, separate fixed identity details from flexible traits, remove contradictory examples, and update outdated character information.
Technical takeaway: Weak character definitions cause ambiguity, while conflicting instructions create competing constraints during generation. Both can produce apparent memory failures even when the underlying information has been stored correctly.
6. The AI Model Summarizes or Loses Older Conversation Details
Long-running AI character conversations often contain more information than an application can supply to the model in a single request. To manage this constraint, a platform may truncate older messages, generate summaries, or retrieve selected information from stored conversation history. These strategies help maintain continuity, but each introduces a different way for important details to become unavailable.
The distinction matters because conversation summarization, message truncation, and memory retrieval are separate operations. They can produce similar symptoms, but they lose or exclude information through different mechanisms.
Conversation Summarization: When Compression Removes Important Facts
A conversation summary condenses a longer interaction into a smaller representation. A system may use a language model to identify major events, relationships, preferences, and unresolved storylines, then retain that summary for later requests. Generated summaries can omit details or introduce unsupported information, so review and correct them before relying on them for continuity.
However, summarization is generally lossy. The resulting text cannot preserve every detail of the original conversation when it is substantially shorter. The summary may preserve the main storyline while omitting exact dates, minor characters, specific dialogue, or conditions attached to an earlier decision.
For example, a long roleplay might establish that a detective promised to meet Emma at a railway station at 6 p.m. A summary could preserve the fact that the detective agreed to meet Emma but omit the time. When the conversation resumes, the character may remember the meeting but fail to recall when it was scheduled.
Summary quality also depends on what the summarization process is instructed to preserve. A summary optimized for narrative continuity may retain major plot developments but discard precise facts that become important later.
Message Truncation: When Older Messages Leave the Active Context
Truncation occurs when the application excludes some messages from the sequence supplied to the model. This may happen because the accumulated prompt approaches the context-window budget or because the platform deliberately retains only a selected portion of the conversation.
Unlike summarization, truncation does not necessarily create a compressed representation of the omitted messages. If the application removes an earlier statement without preserving its important facts elsewhere, those details are simply unavailable to the model in that request.
The original messages may still exist in the conversation database. The limitation concerns the information included in the active inference context, not necessarily the persistence of the historical transcript.
Memory Retrieval: When Stored Information Is Not Returned
Some AI character systems maintain separate memory stores or search previous conversation records when responding to a new message. Retrieval may use keyword matching, metadata filters, semantic embeddings, ranking models, or combinations of these techniques.
A retrieval system can miss relevant information for several reasons:
- The query does not match the wording or meaning of the stored record closely enough.
- The correct record ranks below a retrieval limit and is excluded from the results.
- Metadata filters exclude the relevant memory.
- The retrieved information is shortened or omitted during prompt construction because of the token budget.
- Multiple records contain conflicting or outdated versions of the same fact.
For example, the system may have stored a fact about Emma’s appointment but fail to retrieve it when the user asks, “When was the detective supposed to meet his sister?” The fact still exists in storage, but it is not supplied to the model for that response.
Why These Mechanisms Must Be Diagnosed Separately
Consider a character that forgets an important event from a long conversation. The event may have disappeared from the active context through truncation, been omitted from a generated summary, or remained in persistent storage but failed to appear in retrieval results.
Each possibility requires a different response. Increasing the context window may help with truncation, improving summary instructions may preserve important facts, and adjusting retrieval or ranking may help recover stored information. None of these changes necessarily fixes the other failure modes.
Implementations vary considerably across AI character platforms. Some primarily supply recent chat messages, while others combine summaries, persistent memory, retrieval systems, or other context-management techniques. We should not assume that every platform uses a separate vector database or automatically summarizes older conversations.
Technical takeaway: An AI character may lose access to an earlier detail because it was truncated, compressed out of a summary, or missed during retrieval. Determining which mechanism failed is essential to improving recall without incorrectly attributing every problem to the language model itself.
7. The Platform Has a Temporary Error or Memory Synchronization Issue
An AI character may lose access to previously established information because of a failure in the application’s session-management, storage, or synchronization layers. Unlike context-window limitations or incomplete memory extraction, these problems occur when the platform fails to save, restore, or retrieve the expected conversation state.
A typical AI character application may maintain several types of state: the message history, character configuration, persistent memory records, and metadata identifying the current conversation. These components may be stored separately and updated through different application services. If one component fails to update or load correctly, the character may receive an incomplete representation of the conversation.
However, a character forgetting a detail does not automatically indicate a software defect. The underlying cause may still be context truncation, unavailable persistent memory, or a retrieval failure.
Failed Writes and Incomplete Persistence
When a user sends a message, the application typically records the message and may trigger additional operations, such as updating a summary or extracting a persistent memory.
These operations do not necessarily occur as one atomic transaction. A message might be saved successfully while a subsequent memory update fails. For example, the conversation transcript may contain a newly established relationship, but the memory service may fail to store the corresponding fact because of a timeout or database error.
If the platform relies on that memory record in later sessions, the character may appear to have forgotten information that remains visible in the original chat.
Session Restoration and Conversation State
AI character platforms often associate messages and saved information with conversation identifiers, user accounts, or session metadata. When a conversation is reopened, the application must load the appropriate state and construct the context required for the next response.
A session-restoration problem can occur if the application loads the wrong conversation, fails to restore recent messages, or associates a request with an unexpected session identifier. In these cases, the model may receive incomplete history even though the user expects the previous state to be restored.
This is particularly relevant when a platform distinguishes between separate chats, character-specific memory, and account-level information. Whether information should carry across those boundaries depends on the platform’s design.
Stale Reads and Synchronization Delays
Some systems update conversation history and memory records asynchronously. A memory extraction service, database replica, or synchronization process may not reflect the latest update immediately.
For example, a character might receive a new fact in one session, but a subsequent request may read an older version of the memory record. This is a possible stale-read scenario: the information has been written or updated somewhere in the system, but the component serving the request has not yet observed the latest state.
Synchronization issues can also arise when an application maintains local and server-side state across devices. The exact behavior depends on the architecture; not every platform uses asynchronous memory services or replicated storage.
How to Distinguish Technical Failures From Normal Memory Limitations
A useful diagnosis begins by identifying what was actually saved and what the model received.
For developers, inspect the relevant stages of the request:
- Message persistence: Confirm that the original message was committed to storage.
- Memory update: Check whether the expected memory record was created or modified.
- Session restoration: Verify that the correct conversation and character state were loaded.
- Retrieval results: Determine whether the expected record was returned for the current request.
- Prompt construction: Confirm that the relevant information was included in the model’s input.
Application logs, timestamps, request identifiers, and storage records can help identify where the expected state was lost. If the information reaches the model correctly but the response is still inconsistent, the issue may lie in generation rather than persistence.
For users, practical checks include refreshing the session, confirming the correct account and conversation are open, checking whether the information remains in chat history or saved memories, and consulting the platform’s service-status information if multiple features are failing.
Technical takeaway: Session and persistence failures can make previously saved information unavailable, but they should not be assumed without evidence. Tracing a fact through storage, session restoration, retrieval, and prompt construction is the most reliable way to distinguish an application-level fault from an ordinary AI memory limitation.
Other Continuity Problems That Can Look Like Forgetting
Not every continuity failure means that a fact was deleted. An AI character may have the information available but struggle to use it consistently, preserve its chronology, resolve a correction, or transfer it to a different model. These related problems are worth distinguishing because each calls for a different fix.
Context Saturation and Context Rot
Context saturation occurs when the active prompt approaches its token budget. The application then has to make trade-offs, such as removing older messages, compressing them into a summary, or selecting only part of the available history. The result may be loss of detail even when the original transcript remains stored.
Context rot describes a related but different problem: as the prompt becomes longer or more crowded, the model may become less reliable at locating, weighing, or applying a particular detail. It is not a single universal failure mode with one agreed threshold, and it is not identical to exceeding the context-window limit. A model can fit the full prompt and still overlook information buried among competing instructions or many similar details.
To investigate either problem, test a specific fact in a short conversation and again after the context grows. Keep the question and wording as consistent as possible. If performance declines only in the longer chat, reduce irrelevant context, preserve a compact summary, and explicitly restate details that are essential to the next scene. This can also contribute to long-conversation drift, where character behavior or story continuity gradually diverges because important details are no longer available or consistently applied.
Personality Drift and Loop Behavior
Personality drift occurs when a character gradually changes its voice, preferences, values, or relationship behavior. Possible causes include weak or conflicting character instructions, earlier characterization falling out of the active context, summaries that omit defining traits, or a model that follows the latest conversational tone more strongly than the original persona. Drift does not by itself prove that saved memory was lost.
Loop behavior is repeated wording, questions, actions, or story beats. It can result from repetitive recent context, ambiguous instructions, weak tracking of the current scene state, or generation behavior that reinforces an existing pattern. To reduce loops, state what has already happened, identify the current scene or task state, and give the character a clear next action rather than repeating the same prompt. If the loop appears suddenly across otherwise unrelated chats, check for platform or model changes as well.
Story Drift and Hallucinations
Story drift occurs when an AI character gradually departs from established events, relationships, or the current state of a narrative. Personality drift changes how the character behaves; story drift changes what the character appears to know or what it treats as having happened. Both can develop when earlier context is omitted, summaries lose details, or instructions conflict.
Hallucinations are different. A hallucination occurs when the model generates information that is unsupported, fabricated, or inconsistent with the available evidence. In an AI character conversation, it might invent a meeting that never happened, give a different name for an established character, or claim that a promise was fulfilled when the story never confirmed it. A hallucination can occur even when the correct information is present in the prompt, so it is not always caused by missing memory.
These problems can overlap: a character may lose an earlier detail and then invent a replacement. To reduce this risk, keep the current story state explicit, distinguish confirmed facts from suspicions, and encourage the character to ask for clarification rather than inventing an answer when a key detail is unavailable.
Update Handling and Temporal Consistency
A reliable memory system must handle changes, not just accumulate facts. If a user corrects a name, changes a preference, or updates a relationship, the system should distinguish the current value from the outdated one. Without an update policy, both versions may remain in memory and retrieval may surface the wrong one. Where possible, make corrections explicit and mark superseded information as outdated instead of merely adding another contradictory note.
Temporal handling is a separate challenge. A character may remember an event but confuse when it happened, treat an old preference as current, or place events in the wrong order. Memory notes are more useful when they distinguish stable facts from time-sensitive states and include dates, sequence, or status where those details matter. For example, ‘Mira worked at the clinic last year’ should not be stored as if she still works there today.
Portability, Model Dependence, and Reconstruction
Memories do not always transfer cleanly between platforms. One service may store a character’s history as a short summary, while another uses structured fields, character cards, or searchable notes. Even if the data can be exported, a different platform may interpret it differently or have different limits on how much of it can be included in a prompt. This is the portability problem: the information may move, but its behavior and meaning may not transfer perfectly.
Memory can also be model-dependent. Different models may follow instructions differently, handle long contexts with different reliability, or interpret the same note in different ways. A memory format that works well with one model may need clearer wording or a different structure with another. Model independence should therefore be treated as a design goal to test, not an automatic property of saved memory.
Finally, storing isolated facts is not the same as reconstructing an event. A note such as ‘the character promised to help Alex’ may omit why the promise was made, when it happened, what followed, and whether it was fulfilled. Without that relational and chronological context, the model may repeat the fact but fail to continue the story coherently. For important storylines, preserve a concise event sequence, current state, unresolved commitments, and the latest confirmed facts—not just a list of names and attributes.
These issues overlap with the seven main causes above, but they are not interchangeable. A context problem calls for better context management; a stale memory calls for correction and update handling; a loop calls for state-aware prompting; and a portability problem calls for testing the exported memory with the destination platform and model.
How to Fix AI Characters That Keep Forgetting Conversations
Fixing AI character memory problems starts with identifying where the information is being lost. The cause may be context-window truncation, missing persistent memory, incomplete memory extraction, ineffective retrieval, conflicting character instructions, or an application-level state error. Each problem requires a different intervention.
For users, the first step is to test whether the character forgets information within the same chat or only after starting a new session. For developers, the more reliable approach is to trace a known fact through conversation storage, memory extraction, retrieval, prompt construction, and response generation. A quick symptom-to-solution guide can help users choose a sensible first check before trying multiple fixes. Users should focus on settings and available memory controls; developers can inspect stored records, retrieval results, and the actual model input.
Quick Troubleshooting: Symptoms, Likely Causes, and Fixes
Use this table as a starting point. The same symptom can have more than one cause, so treat each result as a clue rather than a definitive diagnosis.
| What you notice | Possible cause | What to try first |
| The character forgets older events in a long chat. | Older messages may be outside the active context, or a summary may have dropped key details. | Create a concise continuity summary and preserve exact names, relationships, and unresolved events. |
| It remembers in one chat but not a new chat. | Cross-session memory may be unavailable, disabled, or not retrieved. | Check memory settings and test a non-sensitive fact in a separate chat without repeating the answer. |
| It remembers names but mixes up relationships or event order. | Memory notes may lack context, timestamps, or a clear current state. | Update the relationship and event notes; mark outdated information as superseded. |
| It contradicts a fact that was just stated. | The model may be ignoring or misinterpreting available context, or instructions may conflict. | Restate the fact clearly, check for contradictory instructions, and test whether the problem repeats. |
| It invents a meeting, promise, or event that never happened. | The model may be hallucinating or filling a gap in the story. | Correct the record, identify confirmed facts, and ask the character to clarify when information is missing. |
Trace One Fact Through Four Checkpoints
Trace one specific fact through four checkpoints: **Stored**—does the saved-memory view or database contain it? **Retrieved**—was that memory selected for the reply? **Included**—did it reach the actual prompt or context sent to the model? **Used**—did the model follow the fact when generating its answer? The first checkpoint that fails narrows the likely cause; it does not prove the cause on its own.
Most users can check saved memories and compare responses across chats. Developers may also be able to inspect retrieval results, assembled prompts, and logs. If a platform does not expose those internals, report the observed failure without assuming which hidden stage caused it.
Three Practical Examples: Find Where Memory Failed
Use the same four checkpoints for different continuity problems. These examples show how to move from a visible symptom to a testable explanation and a targeted fix.
Example 1: The Character Forgets a Relationship
Symptom: A character remembers Alex and Morgan but suddenly treats them as strangers instead of siblings.
Likely cause: The relationship may never have been saved explicitly, a summary may have dropped the connection, or conflicting notes may describe the characters differently.
Diagnostic test: Check whether the saved memory states the relationship clearly. If it does, see whether the platform makes that note available in a later reply. If the prompt is not inspectable, test with a direct, neutral question and compare the answer with the saved note.
Fix: Store the relationship as an explicit fact—“Alex and Morgan are siblings”—and remove contradictory or outdated versions. Avoid relying on scattered dialogue to preserve a relationship.
Example 2: The Character Forgets Whether a Promise Was Kept
Symptom: The character remembers promising to help but later speaks as if the promise was never fulfilled—or claims it was completed when it was not.
Likely cause: The memory preserves the promise but not the event sequence or its current status. A summary may have collapsed “promised,” “started,” and “completed” into one vague note.
Diagnostic test: Look for three separate details: what was promised, what happened afterward, and whether the commitment is fulfilled, pending, or unresolved. If the note contains only the promise, the timeline is incomplete.
Fix: Keep a short event record with dates or story order and a current-state line, such as “Promise to help Alex: made yesterday; not yet fulfilled.” Update the status only when the story establishes a change.
Example 3: A Fact Works in One Chat but Disappears in a New Chat
Symptom: The character correctly recalls a fictional hometown in the current conversation but cannot answer in a separate chat.
Likely cause: The fact may exist only in the original chat history, persistent memory may be unavailable or disabled, or the new session may not retrieve the saved record.
Diagnostic test: Use a distinctive, non-sensitive fact. Confirm it in the original chat, check the available saved-memory controls, then test a new chat without repeating the fact. Do not delete the original chat while comparing results.
Fix: If the system supports cross-chat memory, save the fact in its supported memory area and confirm it appears there. If it does not support persistent recall, keep a concise handoff note and provide it at the start of the new session. Without access to internal logs, you may identify the failure pattern but not the exact hidden mechanism.
Across all three examples, do not immediately rewrite the character or buy a larger context window. First establish whether the fact was stored, made available, included in the input, and followed in the answer.
1. Start a New Chat to Test Whether the Problem Persists
Starting a new chat is a useful diagnostic test for determining whether an AI character’s memory problem is related to the active conversation context or to cross-session memory. However, it is important to distinguish a controlled test from a workaround: a new conversation does not automatically fix the underlying issue, and it may not preserve the context of the original chat.
In a long conversation, the application may remove older messages from the active prompt to remain within the model’s context-window budget. Opening a new chat creates a different conversation context, often with a smaller message history. This can help determine whether the original conversation’s length contributes to inconsistent responses.
How to test it:
- Choose a distinctive, non-sensitive fact, such as a fictional character’s hometown or a specific event in a story.
- Introduce the fact in the original conversation and confirm that the AI character uses it correctly.
- Continue the conversation for several exchanges, then ask about the same fact again.
- Open a new chat with the same character and ask about the fact without repeating it.
- Compare the responses and check any saved-memory interface the platform provides.
If the character recalls the fact in the original chat but not in the new one, the platform may not support cross-session memory, or the relevant memory may not be available in the new session. If recall deteriorates only after a long exchange, context management or summarization may be contributing to the problem.
These results are diagnostic clues, not definitive proof. Starting a new chat changes several variables at once, including conversation history and possibly session state. A more rigorous diagnosis requires checking whether the fact was saved and whether it was included in the model’s input.
For developers, compare the assembled prompts and retrieved memory records from both sessions. If the fact appears in the original prompt but not in the new one, investigate context construction and memory retrieval before attributing the behavior to the language model itself.
Important: Do not delete the original conversation during testing. Preserve it so you can compare the history, available memory, and responses across sessions.
2. Save Important Details Using the Platform’s Memory Features
Saving important information through a platform’s memory features can improve continuity across long conversations and separate chat sessions. However, the effectiveness of this approach depends on how the platform stores memories, retrieves them, and incorporates them into the language model’s context.
A persistent memory system typically separates selected facts from the active conversation history. Instead of relying entirely on earlier messages remaining within the context window, the application can store important information and retrieve it when a later response requires it.
What Information Should You Save?
Prioritize facts that must remain consistent throughout a conversation or across sessions:
- Character details: Names, identities, backgrounds, and established relationships.
- Story continuity: Important events, previous decisions, unresolved conflicts, and current objectives.
- User preferences: Preferred communication styles or other relevant preferences, where supported.
- Persistent constraints: Rules, boundaries, and conditions that should continue to apply.
For example, a roleplay memory might state: Emma is the detective’s younger sister. The detective lives in London and has promised to meet Emma at the railway station at 6 p.m.
This concise record preserves specific relationships and an exact appointment time. It is more useful for continuity than a vague summary stating that the detective has family responsibilities.
How to Save Information Effectively
If the platform offers manual memory controls, use them to save critical facts explicitly. Some systems provide pinned memories, character notes, persistent user profiles, or knowledge files. Other platforms may generate memories automatically, without allowing users to control every stored detail.
Keep memory records concise, unambiguous, and easy to update. When a fact changes, revise the existing record rather than leaving conflicting versions in different notes. Separate stable background information from temporary events, such as an appointment that has already passed.
For developers, the objective is to preserve the information needed for future responses without filling the memory store with redundant or outdated records. Structured fields can help maintain entities, relationships, timestamps, and current state, while retrieval metadata can improve the selection of relevant facts.
Verify That Saved Memory Is Actually Used
Saving a fact does not guarantee that the model will receive it during a later request. The application must retrieve the record and include it in the context supplied for inference.
To test this, save a distinctive, non-sensitive fact, start a new conversation if cross-session memory is supported, and ask a question that requires the fact. If the character fails to recall it, check whether the memory is still saved and whether the platform offers a way to inspect or search stored memories.
For developers, trace the fact through storage, retrieval, and prompt construction. This distinguishes a failed memory write from an unsuccessful retrieval or a generation error.
Technical takeaway: Persistent memory helps preserve information beyond the active context, but reliable recall requires three things: the fact must be stored correctly, retrieved when relevant, and supplied to the model in a form it can use.
3. Shorten Long Conversations When Recall Becomes Inconsistent
When an AI character begins forgetting earlier details during a lengthy conversation, reducing the amount of active conversation history can help. The underlying issue may be context-window pressure: the application cannot include every previous message in the prompt, so it must select, truncate, or summarize the available history.
However, simply shortening a conversation is not always sufficient. The goal is to reduce unnecessary context while preserving the information required for continuity.
Why Long Conversations Can Reduce Recall Accuracy
Every message included in an inference request consumes tokens. The context budget may also need to accommodate system instructions, character definitions, retrieved memories, and the model’s response.
As the conversation grows, the application may remove older messages or summarize them to stay within the available budget. If important details are omitted, the model may no longer have enough information to answer questions about earlier events.
Even when the entire conversation fits within the context window, a long prompt can make relevant information harder for the model to use consistently. A larger context does not guarantee that every detail will receive equal attention.
How to Reduce Context Pressure Without Losing Important Details
- Create a conversation summary.
Before moving to a new chat, summarize the established facts, important events, character relationships, decisions, and unresolved questions. Preserve exact names, dates, and conditions where accuracy matters.
- Remove redundant background information.
Avoid repeatedly including lengthy character descriptions or explanations that are already captured in stable character instructions or supported memory features. Keep essential constraints explicit.
- Separate stable facts from temporary events.
Character identity and relationships may belong in a persistent character profile. Current objectives, recent decisions, and unfinished storylines may belong in a shorter session summary.
- Start a new conversation when appropriate.
If the current thread has become difficult to manage, open a new chat and provide the summary. This creates a smaller initial context, but continuity depends on how accurately the summary preserves the previous conversation.
A Technical Approach for Developers
Developers can manage context pressure by tracking token usage and prioritizing information before prompt construction. A context-management strategy might preserve system instructions and essential character facts, retain recent messages, and summarize older exchanges.
The prompt builder should account for the model’s context limit, the expected response length, and any additional tokens required by the platform. It should also avoid discarding facts that are important to unresolved tasks or established relationships.
For applications with persistent memory, a compact summary can complement retrieval rather than replace it. The summary provides broad conversational state, while memory retrieval supplies specific facts needed for the current query.
Technical takeaway: Shortening a conversation helps when unnecessary history consumes the context budget or obscures relevant details. The most reliable approach is to compress redundant history while explicitly preserving facts, relationships, and events that future responses must use.
4. Add Essential Facts to the Character Definition
Adding essential facts to an AI character’s definition can improve consistency by making important information available whenever the platform includes that definition in the model’s prompt. This is particularly useful for stable details such as a character’s identity, background, relationships, motivations, and behavioral constraints.
However, a character definition is not the same as persistent conversational memory. A definition typically describes the character’s established attributes, while memory records may preserve information acquired during interactions. Updating the definition helps maintain stable facts, but it does not automatically preserve every event that occurs during a conversation.
Which Facts Belong in a Character Definition?
Prioritize information that should remain consistent across different conversations:
- Identity and background: Name, age where relevant, occupation, location, and personal history.
- Relationships: Family members, friends, rivals, and established connections.
- Personality and behavior: Specific traits, motivations, communication style, and behavioral constraints.
- Established facts: Important details that should not change between responses.
- Continuity rules: Conditions the character should respect when discussing its background or relationships.
For example, instead of describing a character simply as “a detective with a complicated family,” provide a more specific definition:
The detective lives in London and has a younger sister named Emma. He is protective of Emma but rarely discusses his family with strangers. These details remain consistent unless the story explicitly establishes a change.
This definition distinguishes fixed facts from behavioral traits. It gives the model clearer information to use when generating responses.
Why Explicit Character Facts Improve Consistency
Character definitions often become part of the prompt supplied to the language model. Explicit facts reduce ambiguity and give the model a stable reference when the same details arise in different conversations.
Vague descriptions leave more room for the model to generate plausible but inconsistent information. Conflicting instructions can create similar problems when one part of a character profile contradicts another.
Keep essential facts concise, remove outdated details, and resolve contradictions. Avoid filling the definition with the entire conversation history, as this can consume context that would be better used for recent messages or relevant memories.
What Developers Should Consider
For developers building AI character systems, character definitions should be treated as a distinct source of information during prompt construction. Stable character attributes can be separated from session-specific events and retrieved memories.
The application should also manage conflicting information deliberately. For example, if the character definition says Emma is 25 but a newer story event establishes that she is now 26, the system should determine whether the change is intentional and update the appropriate record rather than repeatedly supplying contradictory facts.
Finally, verify that the definition actually reaches the model. If prompt construction truncates or excludes the relevant section, editing the character profile alone will not solve the problem.
Technical takeaway: A well-structured character definition provides a stable reference for identity and behavior. It improves consistency when the relevant facts are included in the prompt, but it cannot replace persistent memory, effective context management, or reliable retrieval of changing conversational details.
5. Use Memory Notes or Summaries for Long Roleplay Stories
Long-running AI roleplay conversations can accumulate hundreds or thousands of messages containing character relationships, plot developments, decisions, and unresolved events. Keeping the entire history in every model request may be impractical because of context-window limits and prompt-construction constraints. Memory notes and conversation summaries help preserve essential information without requiring the application to include every previous message.
Although these methods serve a similar purpose, they are not identical. A memory note preserves selected facts, while a conversation summary captures the broader state of an ongoing interaction.
Memory Notes vs. Conversation Summaries
Memory notes work best for specific details that must remain consistent. These might include character relationships, important dates, personal preferences, established rules, and long-term objectives.
Conversation summaries provide a compact account of what has happened. They can preserve major events, recent decisions, unresolved conflicts, and the current position of a story.
For example, a roleplay system might maintain the following memory note:
Emma is the detective’s younger sister. The detective lives in London and promised to meet her at the railway station at 6 p.m.
A separate session summary might state:
The detective discovered a clue at the warehouse and agreed to meet Emma at the railway station. The investigation remains unresolved, and the next scene begins before their meeting.
The memory note preserves specific facts, while the summary records the current narrative state. Using both can help maintain continuity across long conversations.
How Summarization Can Introduce Information Loss
Summaries are compressed representations of the original conversation. When a system reduces thousands of tokens to a few hundred, some information will inevitably be omitted.
A summary may retain the main storyline but lose an exact date, a minor character’s name, a condition attached to a promise, or the order in which events occurred. If that information is important later, the character may generate an inconsistent response.
To reduce this risk, summaries should prioritize:
- Exact names and relationships.
- Important dates, locations, and conditions.
- Decisions and commitments that affect future events.
- Changes to character relationships or story state.
- Unresolved questions and the next expected action.
Avoid summaries that describe events too generally when precise details matter.
How to Maintain Useful Memory Notes
For users, keep notes short, explicit, and organized. Separate stable character information from events that change as the story progresses. Update outdated notes instead of accumulating contradictory versions.
For developers, a more systematic approach can use structured memory records for stable facts and a rolling summary for the evolving conversation. Each update should preserve critical entities, relationships, temporal details, and unresolved tasks.
Where the application supports it, memory records can also include metadata such as timestamps, source messages, or confidence indicators. This helps distinguish a recent event from an outdated fact and makes conflicting records easier to investigate.
The application should retrieve only the information relevant to the current request. Inserting every memory note into every prompt can waste context and introduce unnecessary details.
Verify That the Summary Preserves Critical Facts
After updating a summary, test it against the original conversation. Check whether essential names, relationships, decisions, and chronological details remain accurate. For important facts, compare the summary with the original source rather than assuming the summarization process preserved everything correctly.
Technical takeaway: Memory notes preserve specific facts, while summaries compress the broader conversation state. Used together, they can reduce context pressure and improve roleplay continuity, provided that summarization preserves important details and the application supplies the relevant information when generating each response.
6. Check Memory Settings and Available Features
When an AI character repeatedly forgets information, verify that the platform supports the type of memory you expect and that the relevant features are enabled. Memory capabilities can differ between platforms, accounts, characters, and individual conversations. Some services provide only conversation history, while others offer pinned facts, persistent user memories, character notes, or automated memory retrieval.
The key is to determine whether the missing information was never saved, was saved but is unavailable in the current session, or was retrieved but not used correctly.
Identify Which Memory Features the Platform Supports
Start by examining the platform’s settings, character configuration, and documentation. Look for features such as:
- Persistent memory: Stores selected information for use across conversations.
- Pinned memories: Keeps specific facts readily accessible within supported chats.
- Character definitions: Preserves stable identity, background, and personality information.
- Conversation summaries: Retains a condensed representation of earlier exchanges.
- Knowledge files or lorebooks: Supplies relevant background information when supported by the platform.
These features are not interchangeable. A character definition may establish a permanent background fact, while persistent memory may retain something learned during an interaction. A saved conversation transcript does not necessarily mean the system can retrieve every detail from it.
Check Configuration and Subscription Limitations
Some platforms allow memory features to be enabled or disabled. Others restrict particular capabilities by account type, subscription, or model configuration.
Confirm whether the relevant feature is available to your account and whether it applies to the conversation you are testing. Do not assume that upgrading will resolve memory problems: a paid plan may offer additional capabilities without guaranteeing accurate recall.
For developers, inspect the feature flags, account entitlements, character-level settings, and prompt-construction logic that determine whether memory is available to a request.
Verify That the Feature Works as Expected
Save a distinctive, non-sensitive fact using the platform’s supported memory controls. Start a new conversation if cross-session memory is supported, then ask a question that requires the saved information.
If the character forgets the fact, check whether the memory still exists in the platform’s memory interface. If it does, the next question is whether the application retrieved it and supplied it to the model.
For developers, trace the record through storage, retrieval, and prompt assembly. This helps distinguish a disabled feature from a failed memory write, an unsuccessful retrieval, or an incorrect response.
Technical takeaway: Memory settings determine which capabilities are available, but enabling a feature does not guarantee successful recall. Confirm the feature’s scope, verify that the information is saved, and establish whether it reaches the model before deciding what needs to be fixed.
7. Refresh the Session and Check for Platform Issues
If an AI character suddenly stops recalling information that it previously used correctly, check whether the application has loaded the correct conversation state. A temporary service failure, an incomplete session restore, or a failed memory update can make previously saved information unavailable. However, refreshing the session is a diagnostic step, not a guaranteed fix for every memory problem.
Why Session and Application State Matter
An AI character platform may maintain conversation history, character settings, and persistent memory in separate storage systems. When a user reopens a conversation, the application must retrieve the appropriate records and assemble the context for the next model request.
If this process fails, the model may receive incomplete or outdated information. For example, a conversation message may have been saved successfully while a separate memory update failed. The original fact remains visible in the chat history, but the memory mechanism does not supply it in a later session.
Other possible causes include temporary server errors, stale cached state, interrupted network requests, or synchronization delays. Whether these mechanisms apply depends on the platform’s architecture.
Troubleshooting Steps for Users
Try the following checks in order:
- Refresh the conversation. Reload the page or reopen the chat to determine whether the problem persists after the session state is reloaded.
- Verify the correct account and character. Make sure you have not opened a different account, duplicate character, or separate conversation.
- Inspect the original chat history. Confirm that the message containing the important fact was saved successfully.
- Check saved memory, if available. Determine whether the fact still exists in the platform’s memory interface.
- Check for service disruptions. If chat history, memory features, or other functions are failing simultaneously, consult the platform’s service-status information.
- Retry after a short interval. If the platform reports a temporary issue, allow the service to recover before repeating the test.
Avoid deleting conversation history or resetting memory during initial troubleshooting. Those actions can remove useful evidence or make it harder to determine what went wrong.
Technical Checks for Developers
Developers should trace the expected fact through the application’s state-management pipeline.
- Persistence: Was the original message committed successfully?
- Memory updates: Did any background extraction or memory-writing task complete?
- Session restoration: Was the correct conversation identifier used?
- Consistency: Did the application load the latest available memory record?
- Prompt assembly: Was the expected information included in the model’s actual input?
Request identifiers, timestamps, error logs, and memory-record versions can help isolate the failure. If the correct information reaches the model but the response remains inconsistent, investigate generation behavior instead of assuming a storage fault.
Technical takeaway: Refreshing a session can resolve transient state-loading problems, but persistent memory failures require further diagnosis. Confirm that the correct data was saved, restored, retrieved, and supplied to the model before attributing the issue to a platform bug.
8. Test Whether the Character Remembers Information Across Sessions
An AI character may remember details during an active conversation but fail to recall them after the user starts a new chat. This difference helps identify whether the platform supports cross-session memory and whether stored information remains accessible beyond the original conversation.
Testing across sessions is particularly useful when a character consistently recalls recent messages but forgets established relationships, user preferences, or important roleplay events in later chats.
Understand the Difference Between Session Memory and Persistent Memory
Session memory refers to information available within the current conversation context. It may include recent messages, selected earlier messages, and a summary of the ongoing interaction.
Persistent memory refers to information that the platform stores for potential use in later conversations. Depending on the implementation, this may consist of structured facts, memory notes, summaries, or retrieved records.
These capabilities are separate. A platform can preserve the full conversation transcript without automatically making every detail available in a new chat. Similarly, a character definition may retain stable background information without preserving events from a previous roleplay.
Run a Controlled Cross-Session Test
Use a distinctive, non-sensitive fact that is not already present in the character’s description. For example, establish that a fictional detective has promised to meet Emma at the railway station at 6 p.m.
- Establish the fact. Introduce it naturally in the original conversation.
- Test immediate recall. Ask a question about the meeting to confirm that the character understood the information.
- Check for persistent storage. If the platform provides a memory interface, verify whether the fact was saved.
- Start a new conversation. Open a separate chat with the same character without repeating the information.
- Test recall again. Ask a natural question about the previously established detail.
- Compare the results. Determine whether the fact remains available, disappears only in the new session, or becomes inconsistent after a long conversation.
For a reliable test, avoid putting the answer in the question itself. Asking, “Who was the detective meeting at 6 p.m.?” may reveal too much if the goal is to test whether the character remembers both the person and the event. A more neutral question, such as “What was the detective’s plan for that evening?”, provides a stronger test.
A practical user-side check is to record whether the fact was saved, whether it remains visible in the memory controls, and whether the character recalls it in a new session. If the platform does not expose stored memories or model inputs, you may be able to identify the symptom but not prove whether storage, retrieval, or response generation caused it.
Interpret the Results
| Test result | Possible explanation |
| The character recalls the fact in the original chat but not in a new chat. | Cross-session memory may be unavailable, disabled, or failing to retrieve the fact. |
| The character forgets after many messages in the same chat. | Context truncation, summarization, or message selection may be responsible. |
| The fact appears in saved memory but is not recalled. | Retrieval, prompt construction, or response generation may be failing. |
| The character recalls the fact inconsistently across repeated tests. | Retrieval ranking, competing context, or generation variability may be involved. |
| The character remembers stable background facts but forgets recent events. | The platform may preserve character definitions without reliably storing conversational events. |
These results are diagnostic clues, not definitive proof. Starting a new conversation can change several variables at once, including the active context, memory retrieval, and session configuration.
What Developers Should Inspect
For developers, the most useful comparison is between the model inputs generated for the original and new sessions. Check whether the relevant fact exists in persistent storage, whether the retrieval process returns it, and whether prompt assembly includes it in the new request.
If the fact is present in both model inputs but recall differs, investigate how the model interprets competing information and generates its response. Repeated trials can help distinguish a consistent pipeline failure from variable model behavior.
Technical takeaway: Cross-session testing reveals whether conversational continuity depends on the active chat or on persistent memory. To identify the actual failure, compare storage, retrieval, and model input rather than judging the system solely by its final answer.
How to Make AI Characters Remember Important Details
Making AI characters remember important details requires more than extending the conversation or enabling a memory feature. Long-term consistency depends on how information is recorded, organized, retrieved, and incorporated into the model’s active context.
The most reliable approach is to separate stable character information from evolving conversation events. Core identity, relationships, and behavioral rules should remain consistent. Temporary details, recent decisions, and unresolved story events need a way to persist and reappear when relevant.
The exact implementation depends on the platform. Some AI character applications provide memory notes, character definitions, or lorebooks. Developer-built systems can use structured records, conversation summaries, and retrieval mechanisms to maintain continuity across long interactions.
1. Separate Permanent Character Facts From Conversation Events
Not all information has the same lifespan. A character’s identity may remain unchanged for months, while a promise made during a particular conversation may matter only until an event is resolved.
Mixing these details into one large description makes updates harder and can cause temporary information to compete with essential character facts.
A more reliable memory structure separates information into three categories:
- Stable character facts: Identity, occupation, background, relationships, location, and enduring personality traits.
- Persistent interaction details: User preferences, established relationship changes, recurring commitments, and facts that should carry across sessions.
- Temporary conversation state: Current objectives, recent events, pending decisions, and unresolved questions.
For example, a fictional detective’s profile might state that he lives in London and has a younger sister named Emma. Persistent interaction memory might record that he promised to meet Emma at a railway station at 6 p.m. The current conversation state might track an ongoing investigation and the evidence discovered so far.
Each category serves a different purpose. Stable facts belong in the character definition or an equivalent reference source. Persistent details belong in supported memory storage. Temporary state belongs in a conversation summary or session record that can be updated as events unfold.
Practical takeaway: Organize information by how long it needs to remain valid. This makes memory easier to maintain and reduces conflicts between permanent character traits and changing events.
2. Write Specific, Unambiguous Memory Notes
Memory quality matters as much as memory quantity. A vague note may preserve the general meaning of a conversation while losing the exact detail needed later.
Consider these two examples:
- Vague: The detective has a close relationship with Emma and plans to see her.
- Specific: Emma is the detective’s younger sister. He promised to meet her at the railway station at 6 p.m. tomorrow.
The second note preserves the relationship, commitment, location, and time. These details make the information more useful for future responses.
When writing memory notes, prioritize:
- Exact names and relationships.
- Dates, times, and locations when they matter.
- Decisions and commitments made during the conversation.
- Changes to established relationships or circumstances.
- Conditions, exceptions, and unresolved issues.
Avoid recording every sentence. Preserve the information that would materially change a future response if forgotten.
For systems that support structured memory, separate fields can improve clarity. A record might store a person’s name, relationship, event, time, and status independently rather than combining everything into an ambiguous paragraph.
However, structure alone does not guarantee successful recall. The application must still retrieve the correct record and provide it to the model.
Practical takeaway: Store precise facts rather than broad impressions, especially when names, timelines, relationships, or commitments affect continuity.
Use Pinned Memories Where Available
If the platform supports pinned messages, pinned memories, or a dedicated memory field, use it for a small set of details that must remain easy to access. Good candidates include defining character traits, important relationships, major promises, and facts that would cause a serious continuity error if forgotten. Pinning a message may preserve or prioritize it within that platform, but it does not necessarily make the information permanent or guarantee that every model response will use it.
Avoid pinning the entire conversation. Too many pinned details can reduce their usefulness, and some platforms impose limits or handle pinned content differently. Check what the feature actually does, keep pinned information current, and remove or update entries when circumstances change.
Practical takeaway: Pin only the highest-priority information, and verify that it remains available in the context or memory system used by the platform.
3. Keep a Current-State Note and Update It Often
A maintained current-state note helps preserve what is true now without requiring the entire transcript to remain in the active context. Unlike a chronological recap, it should make the latest situation, active commitments, relationship status, unresolved questions, and next expected actions easy to identify.
A useful summary should describe the situation as it stands now, rather than simply recounting every event in chronological order.
For example, a detective story summary might preserve the following information:
- The detective is investigating a missing painting.
- Emma is his younger sister and is not involved in the investigation.
- A witness reported seeing a suspicious vehicle near the warehouse.
- The detective promised to meet Emma at the station at 6 p.m.
- The identity of the person who took the painting remains unknown.
This summary preserves established facts, important events, and unresolved questions. It also prevents the model from treating an unconfirmed suspicion as a proven fact.
Update the note whenever a meaningful event changes the story. If the meeting takes place, replace the pending commitment with its outcome. If a suspect is cleared, remove the outdated assumption from the current state. If a relationship changes, record both the established relationship and the new development. Keep historical events in a separate history section when they remain relevant, and clearly label what is no longer current.
A summary should not become an archive of every past interaction. Older details that no longer affect the current situation can be removed or retained in a separate history record.
Practical takeaway: Treat the current-state note as a living record, not a static summary. Update it after meaningful developments and make the present state unmistakable.
4. Front-Load and Reinforce Critical Details Without Creating Contradictions
Front-load the essentials: put the facts that must guide the next response near the beginning of the relevant character instructions, memory note, or prompt section when the platform lets you control that order. Prioritize core identity, key relationships, current objectives, important constraints, and unresolved commitments. Front-loading does not expand the model’s context window, but it can make the most important information easier to identify within a crowded prompt.
Reinforcement can improve consistency, but copying the same fact into several places without a clear update strategy can create conflicting versions.
For example, the character definition might state that Emma is the detective’s younger sister. A later memory note might incorrectly describe her as his cousin. If both records enter the active context, the model may produce inconsistent responses.
To prevent this, establish a clear source of truth for stable information. Use conversation memory for changes and events, and update outdated records when circumstances change.
For developers, this can involve assigning priorities to information sources, tracking record versions, and resolving conflicting facts before prompt construction. A newer record should not automatically override an older one unless the system can establish that the change is legitimate.
For character creators, the practical equivalent is to edit the character definition and memory notes when important facts change, rather than adding contradictory explanations.
Practical takeaway: Put essential information where it is likely to be included and used, then maintain one authoritative version. Consistency depends on resolving conflicts as well as preserving details.
Weave Reminders Into the Conversation
When an important fact becomes relevant, briefly reintroduce it in a natural way instead of assuming the character will retrieve an old message. For example: “As Daniel checks his watch, he remembers that he promised to meet Emma at the station at six.” This places the commitment back into the active conversation while keeping the story moving.
Use reminders selectively. Repeating every background detail can clutter the context and make dialogue feel unnatural. Focus on information that affects the next scene, such as a promise, unresolved conflict, relationship change, or current objective. Reminders support memory; they do not replace persistent storage or reliable retrieval.
5. Retrieve Relevant Memories Instead of Loading Everything
For developer-built AI character systems, retrieving relevant information is often more effective than inserting every stored memory into every request.
A large memory collection can consume the context budget and introduce irrelevant details. This may make important facts harder for the model to use, even when those facts are available somewhere in storage.
A retrieval system can select memories based on the current message, relevant entities, conversation state, and metadata. For example, a question about Emma should make the system consider records associated with her relationship to the detective and their planned meeting.
Several techniques can support this process:
- Entity-based retrieval: Find records associated with people, places, objects, and other named entities.
- Semantic retrieval: Identify records with meanings related to the current request, even when the wording differs.
- Metadata filtering: Restrict results by character, conversation, date, or memory type.
- Recency and relevance ranking: Prioritize records that are current and useful for the question.
- Context-budget management: Limit retrieved information to what can fit without displacing essential instructions or recent conversation state.
These techniques are complementary. Semantic similarity alone may retrieve an outdated record, while recency alone may prioritize an irrelevant detail. A well-designed system balances relevance, reliability, and current state.
Retrieved memories should also preserve their meaning. A system that retrieves only the sentence mentioning Emma’s meeting time but omits who Emma is may supply incomplete context.
Practical takeaway: Store enough information to preserve meaning, then retrieve the facts that matter to the current interaction. More memory is not automatically better memory.
Memory Plugins and External Memory Tools
Some AI character systems support extensions, plugins, or external tools that store and retrieve information beyond the active chat. Depending on the platform, these may connect a character to a searchable knowledge base, a vector database, structured memory records, a note system, or a retrieval-augmented generation (RAG) workflow. These tools can help preserve facts across long conversations or sessions, but they are not available in every consumer platform and are not interchangeable with built-in memory features.
A useful external memory setup should do more than save a transcript. It should preserve compact, meaningful records; retrieve the right information for the current question; include relevant results in the prompt; and update or mark outdated facts when the story changes. For long-running roleplay, separate stable character information from event history and the current state. Where possible, retain source messages or timestamps so conflicting records can be checked.
Before installing or configuring a memory plugin, verify that it is compatible with the chat interface and connected model. Check what data it stores, whether it works across sessions, how retrieval is triggered, what privacy or access controls it uses, and whether it consumes part of the model’s context budget. A tool can successfully store a memory yet still fail to retrieve it—or retrieve it without the model applying it correctly.
For platforms without plugin support, use the closest supported alternative: built-in memory controls, pinned details, character notes, lorebooks, a concise current-state summary, or a manually maintained reference document. Do not assume that a plugin can be installed into a hosted platform unless its documentation explicitly supports extensions or integrations.
Practical takeaway: External memory tools can improve persistence and retrieval when the platform supports them, but they do not guarantee perfect recall. Test whether a saved fact is actually retrieved and used before relying on the tool.
6. Test Memory Consistency Over Time
A character that recalls a fact immediately after it is introduced may still fail to remember it later. Long-term consistency should therefore be evaluated across different conversation lengths, sessions, and types of questions.
Use a small set of controlled test facts covering different memory requirements. Include a stable identity fact, a relationship, a specific event, and a detail that changes during the conversation.
Then evaluate whether the character:
- Recalls the fact shortly after it is introduced.
- Preserves it after a long exchange.
- Recalls it in a new session when cross-session memory is supported.
- Uses the latest version after a fact changes.
- Avoids inventing details when the required information is unavailable.
For developers, automated evaluation can compare expected facts with model responses and inspect the context supplied to each request. Track whether failures originate in storage, retrieval, prompt construction, or generation. This provides more useful evidence than measuring recall from final responses alone.
Testing should also include negative cases. If a detail was never established, the character should not confidently invent a specific answer. Reliable continuity includes recognizing uncertainty, not just recalling stored information.
Practical takeaway: Evaluate memory across time, sessions, updates, and uncertain situations. A single successful response does not establish reliable long-term recall.
7. Design for Graceful Recovery When Memory Is Missing
Even a well-designed memory system can fail to retrieve a detail. Reliable AI characters should handle these situations without hallucinating past events, confidently inventing missing facts, or silently changing established information.
When critical information is missing, the character can ask the user to clarify it, acknowledge uncertainty, or continue using only the facts that remain available.
For example, if the detective’s planned meeting time is unavailable, a consistent response would be to ask when the meeting was arranged. Inventing a new time could create a contradiction that affects later conversations.
Developers can support graceful recovery by distinguishing between confirmed facts, inferred information, and unknown details. Memory records may include their source, timestamp, confidence, and update status. The response-generation process can then avoid presenting uncertain information as established history.
For roleplay platforms without these controls, users can reduce disruption by maintaining a concise reference note for essential story facts and reintroducing it when continuity breaks down.
Practical takeaway: Do not design memory systems around perfect recall. Make uncertainty visible and provide a reliable way to restore missing information.
Memory Privacy and Data Control
Memory features and external tools can improve continuity, but they may also store personal details, private roleplay content, or conversation records outside the active chat. Before enabling a memory feature or connecting a third-party tool, check what information it collects, where it is stored, who can access it, and whether it is used or shared beyond the feature you intended to use.
Store only what is useful for continuity. Avoid adding passwords, financial details, identifying information, or other sensitive data to character memories. Where controls are available, review saved entries periodically and remove details that are no longer needed. Check whether deleting a chat also deletes its associated memories; those may be handled separately. For external tools, review permissions and the provider’s privacy terms before connecting an account or exporting a conversation.
For developers, document memory retention, access controls, deletion behavior, and any third-party data flow. A memory system should support correction and removal as well as storage and retrieval. Better recall is not worth retaining more personal information than the feature needs.
| Platform | Main memory approach | Important consideration |
| Character.AI | Pinned Memories and other chat-memory tools; additional memory features may depend on plan | Check the current in-app feature names, limits, and whether information carries into a new chat. |
| Kindroid | Layered memory, including persistent information and retrievable long-term memories | Check which memory layers are enabled, their limits, and what was actually recalled. |
| Replika | Editable memories and automatic personalization from conversation patterns | Memory supports personalization; do not assume complete transcript recall. |
| SillyTavern | Configurable character cards, World Info/lorebooks, and prompt/context management | Lorebook entries must activate and fit into context; the connected model may still ignore details. |
| Janitor AI | Available memory behavior may depend on the current interface, settings, and model connection | Verify the current controls and test what is preserved across sessions before relying on it. |
How to Compare AI Character Memory Systems
AI character systems manage memory in different ways. Some retain selected facts automatically, some rely on summaries or manually saved notes, and others let users configure how character information enters the model prompt. These approaches should be compared by what they actually preserve and retrieve, not by feature names or advertised capacity alone.
Which AI Character System Has the Best Memory?
There is no universal winner. The best fit depends on whether you need continuity within one chat, recall across separate chats, detailed story tracking, editable memory records, or control over the prompt sent to the model.
To compare systems fairly, test the same small set of non-sensitive facts in each one. Include a stable character detail, a relationship, a time-sensitive event, and an unresolved commitment. Check whether each fact is stored, whether it is available in a later conversation, and whether the character uses it accurately.
Separate documented features from your own test results. A setting may be available only on certain plans or configurations, and some systems depend on an external model or extension. If the platform does not expose its stored memories or final prompt, you may be able to identify a recall problem without knowing its exact internal cause.
What to Check Before Choosing a Platform
Look for clear controls to save, review, edit, and delete memory. Check whether saved information carries across chats, how summaries are updated, whether old facts can be corrected, and what happens when the context limit is reached. If a system relies on configurable tools, confirm which parts are built in and which require extra setup.
Do not judge memory quality only by context-window size, a feature label, or a paid tier. Reliable continuity depends on preserving the right details, retrieving them when relevant, supplying them to the model, and using them consistently.
Does Paying for an AI Character Platform Improve Memory?
A paid plan can improve memory-related capabilities when it explicitly provides a larger context window, additional memory controls, or a stronger retrieval feature. However, paying does not guarantee accurate recall. The benefit depends on the feature included and the reason the character is forgetting information.
Free vs. Paid Memory Features
Free and paid plans vary by platform. A free plan may include chat history, character definitions, and basic memory controls. A paid plan may add memory capacity, more advanced retrieval, a larger context window, or access to a different model. Some subscriptions mainly increase message limits or speed and may not improve memory at all.
Check the current plan description rather than assuming that a subscription includes persistent memory. Confirm whether the feature works across separate chats and whether you can inspect or edit saved information.
Does a Larger Context Window Mean Better Memory?
A larger context window lets a model process more tokens in one request. This can help when older messages are being removed to fit the prompt, but it does not ensure that the application includes every relevant message or that the model uses each detail correctly.
Persistent memory solves a different problem: it can preserve selected information for later use. The application must still retrieve that information and include it in the model’s context. A system may benefit from both a larger context window and persistent memory, but neither guarantees perfect recall.
What to Check Before Upgrading to a Paid Plan
- Confirm that the plan includes the specific memory feature you need, not simply higher message limits.
- Check whether the feature carries information across separate chats or only within the current conversation.
- Compare the actual context capacity available to your chosen model and whether the application uses it for conversation history, character instructions, and memory notes.
- Look for controls that let you inspect, edit, or remove saved memories and outdated information.
- Test the current plan with a distinctive, non-sensitive fact before paying. Check whether the fact is saved, whether it is available in a new chat, and whether the character uses it accurately.
Technical takeaway: Upgrade only when a documented paid feature addresses the failure you have identified. If the model already receives the correct information but still contradicts it, a larger context window or higher subscription tier may not solve the problem.
Frequently Asked Questions About why do AI characters forget conversations
Why Do AI Characters Forget What I Said Earlier?
AI characters may forget earlier messages because of context-window limits, incomplete memory storage, or failed memory retrieval. Even when the relevant information reaches the model, it may generate an incorrect response. The exact cause depends on how the platform manages conversation history and memory.
Can AI Characters Remember Previous Chats?
Yes, some AI character platforms support persistent memory across separate chats. They may store selected facts, summaries, or conversation details for later use. However, cross-session memory depends on the platform’s features and settings, and stored information is not always retrieved correctly.
Why Does My AI Character Forget Me After I Close the App?
Closing the app should not necessarily erase saved information. However, the platform may not preserve conversational details across sessions, or it may fail to restore the correct memory when you return. Check whether the conversation was saved and whether persistent memory is enabled.
Can I Make an AI Character Remember Everything?
No. You cannot guarantee that an AI character will remember every message perfectly. Context limits, summarization, selective memory storage, and retrieval errors can cause information loss. You can improve continuity by saving important facts, maintaining concise summaries, and using supported memory features.
Do AI Characters Have Permanent Memory?
Some AI character platforms preserve selected information across sessions, but this is not necessarily permanent or unlimited. Memory may be editable, subject to capacity limits, or affected by account settings and platform changes. Persistent storage also does not guarantee that the character will recall every saved detail.
Does Starting a New Chat Delete an AI Character’s Memory?
Not necessarily. Starting a new chat may reset the active conversation context while leaving persistent memories or character definitions intact. Whether memories carry over depends on the platform, its settings, and how cross-chat memory is implemented.
How Can I Compare AI Character Memory?
There is no universal winner. Compare the memory features that matter to your use case, including cross-chat recall, editable records, summary quality, configuration requirements, and the ability to correct outdated facts. Test the same non-sensitive details across a long conversation and a new chat instead of relying on marketing claims or a single successful response.
Final Thoughts: How to Stop AI Characters From Forgetting Conversations
AI characters forget conversations for different reasons. The problem may involve limited context, missing persistent memory, incomplete summaries, weak character instructions, or a temporary platform issue. Identifying the cause is the first step toward improving continuity.
For everyday users, start by saving important facts, keeping memory notes concise, and maintaining an updated summary of significant story events. Check the platform’s memory settings and test whether information carries over to new conversations. For long-running roleplay, separate permanent character details from changing relationships, commitments, and unresolved events.
If you use a developer-focused system, inspect how conversation history and saved memories enter the model’s prompt. Confirm that important facts are stored, retrieved, and supplied to the model. If the information is already present but the character still contradicts it, investigate response generation and conflicting instructions.
Remember that a larger context window or paid subscription does not guarantee perfect recall. Persistent memory, effective retrieval, and accurate response generation solve different parts of the problem.
The most effective fix depends on where the information is lost. Once you distinguish a context limitation from a memory, instruction, or platform issue, you can choose a solution that addresses the actual cause instead of repeatedly restarting conversations or changing settings without a clear reason.
Author Bio:
Rajkumar RR is a technology writer and the creator behind ProDigitalWeb.com. He covers artificial intelligence, emerging technologies, software, digital tools, and practical tech solutions. His goal is to make complex technology topics easier to understand through clear explanations, useful examples, and actionable guidance. He focuses on helping readers understand how technology works, troubleshoot common problems, and make informed decisions about the tools they use.
Last updated: October 28, 2026